01
AI Systems & Retrieval
LLM pipelines, hypothesis-driven retrieval, source evaluation, grounding, provenance, and evidence quality.
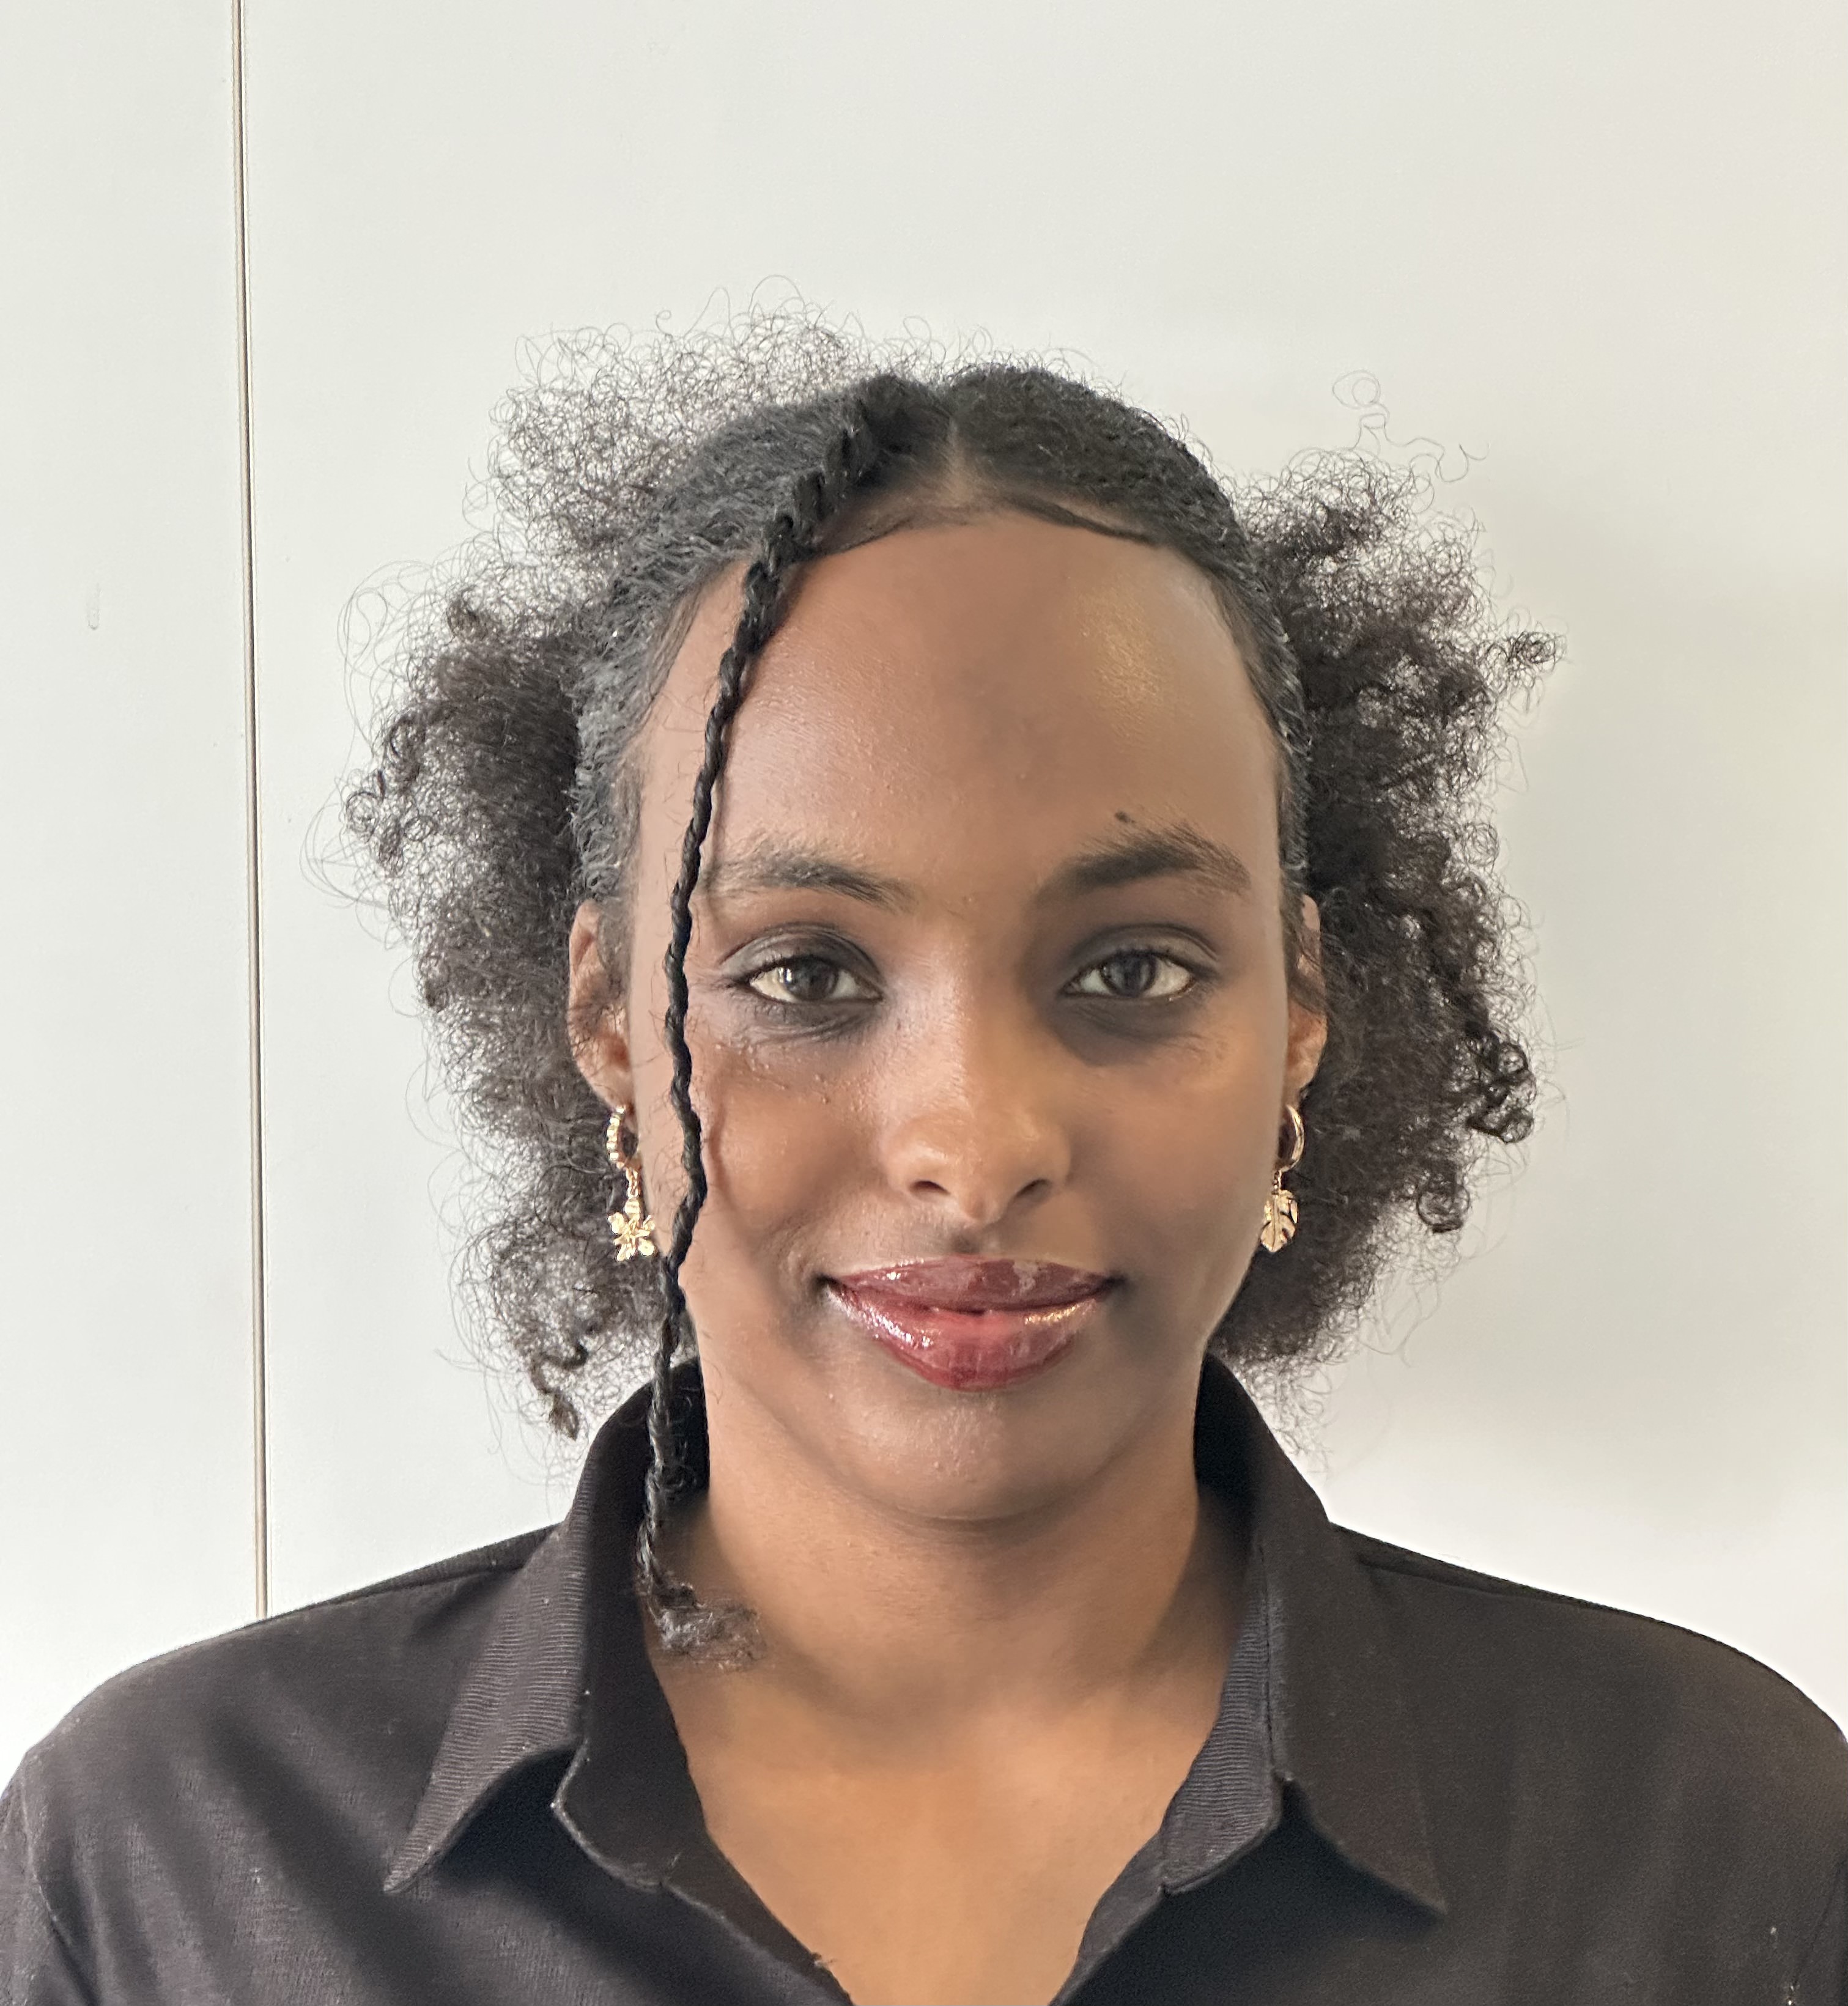
Computer Science & Economics at Harvard
Software engineer building AI systems, data pipelines, and intelligent products across labor-market intelligence, recommender systems, education, and healthcare.
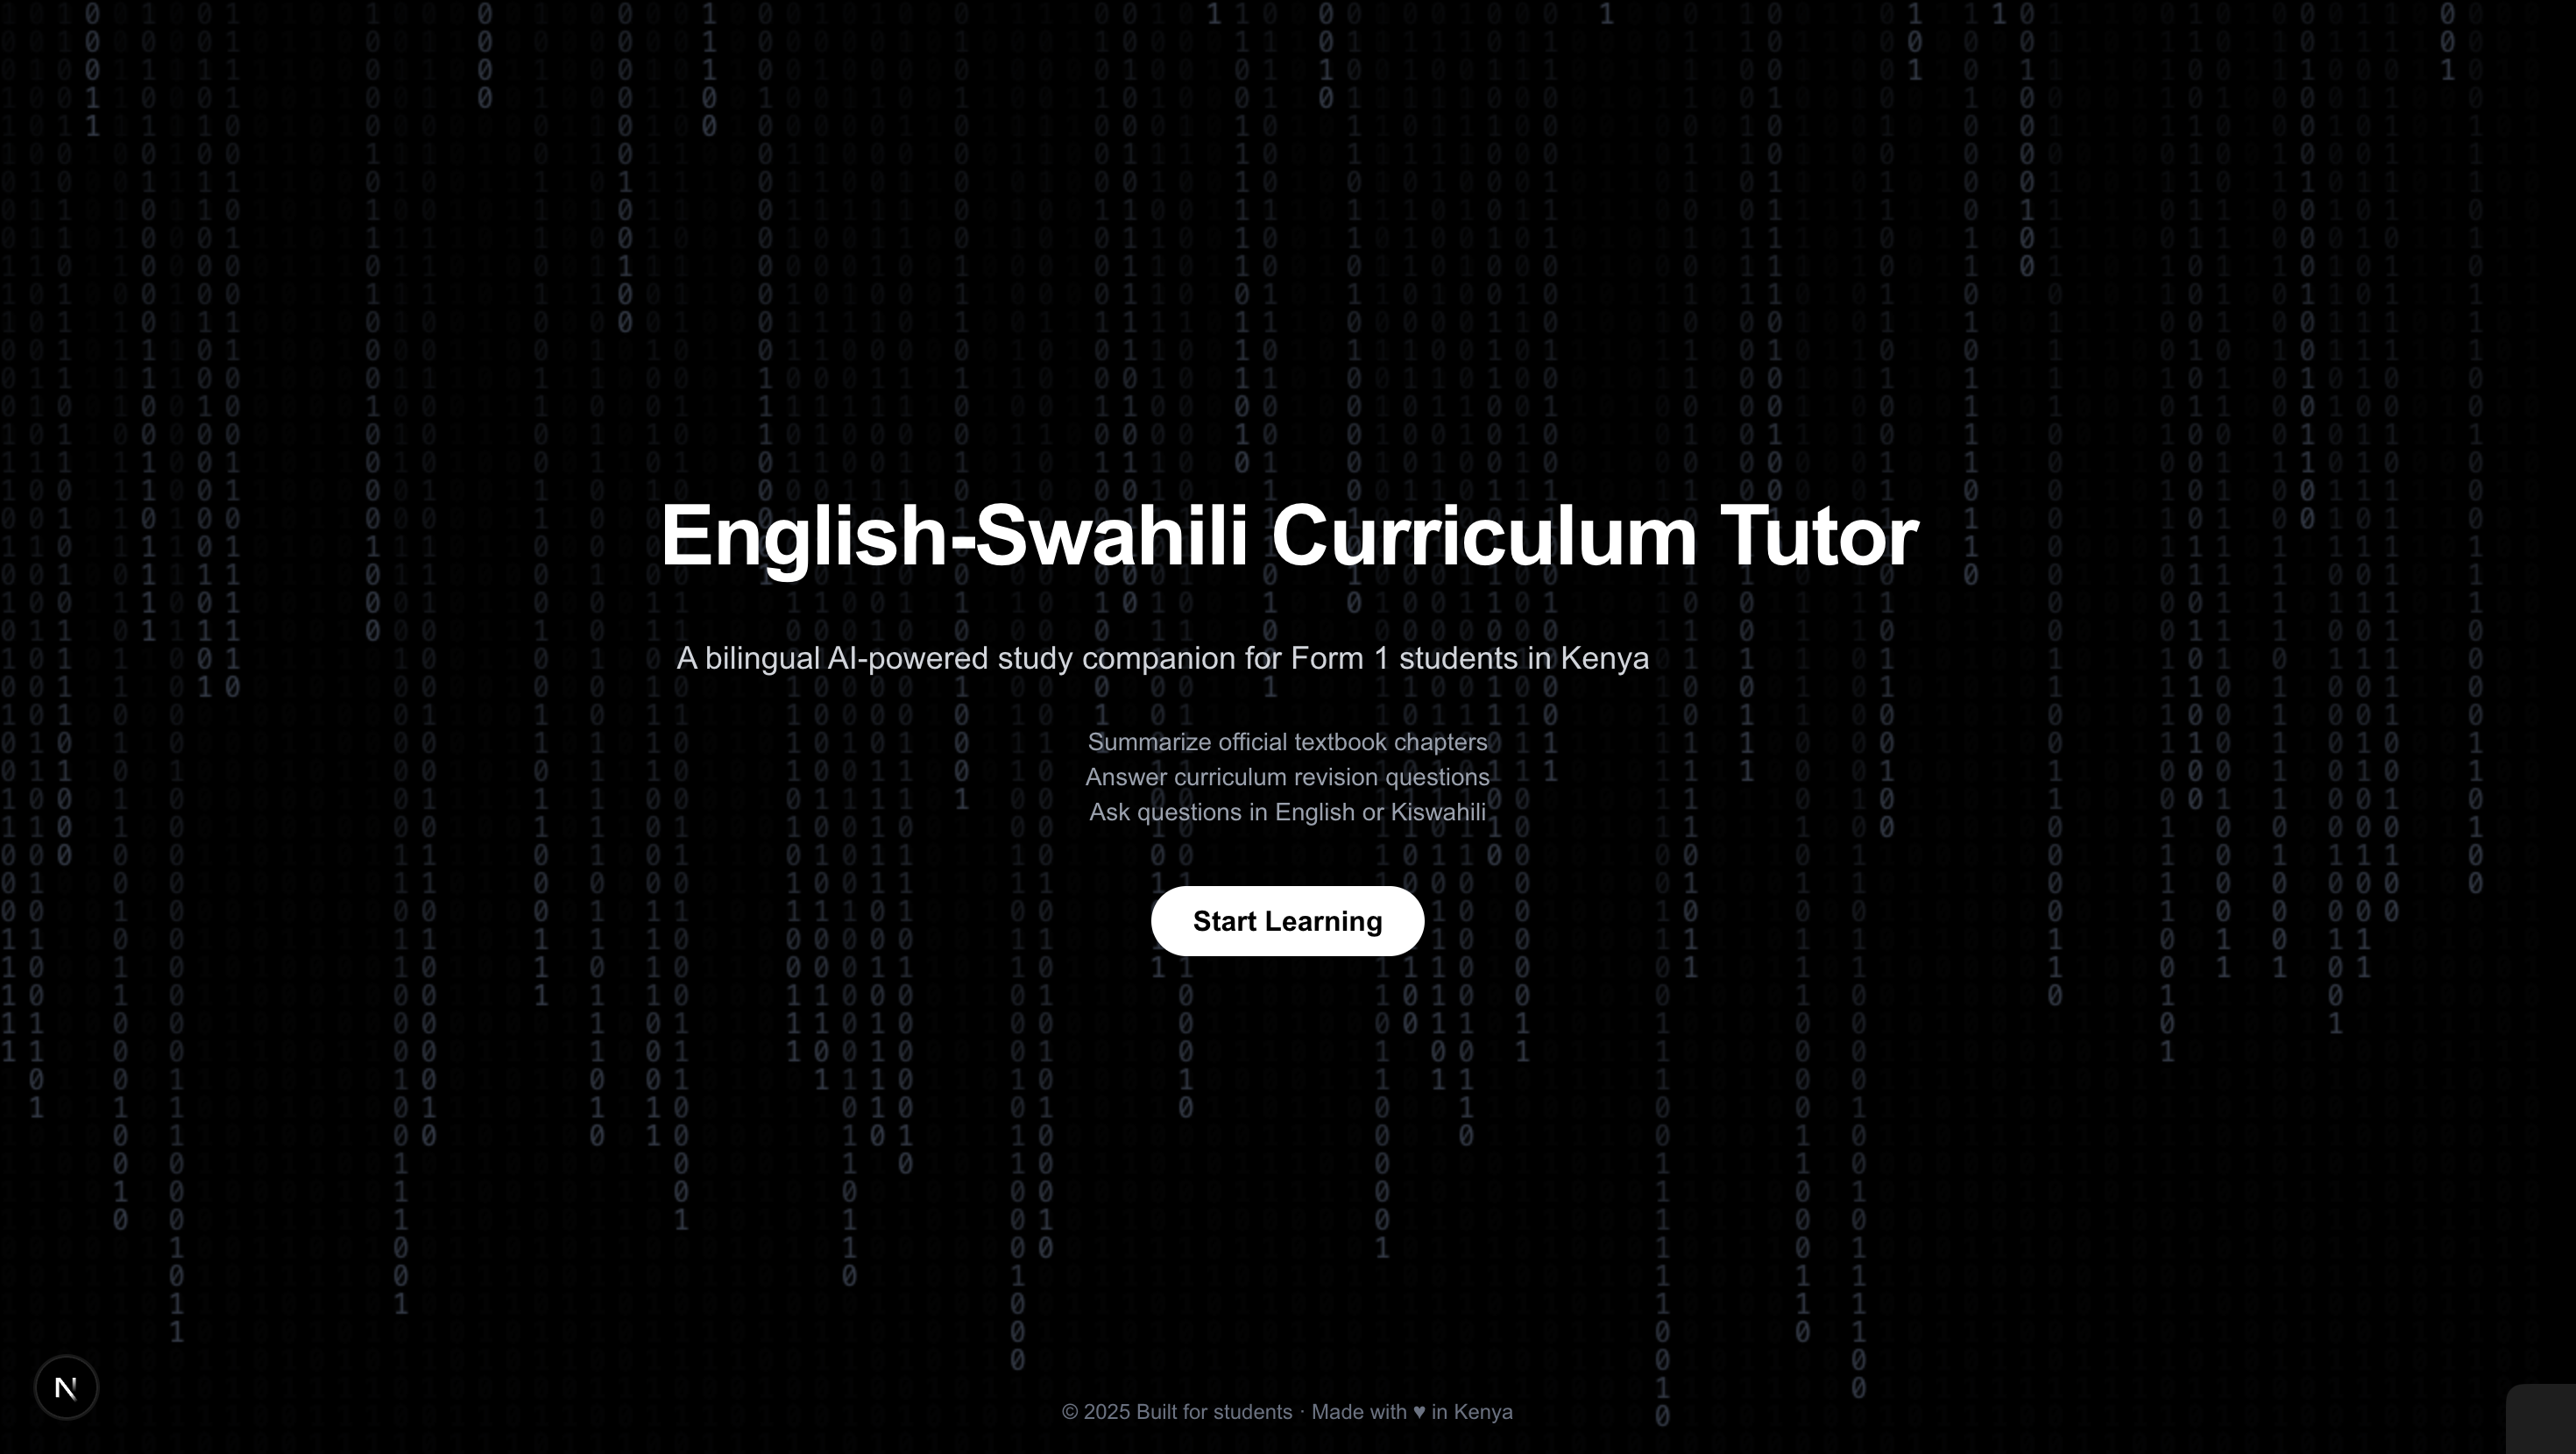
Get in TouchBilingual AI tutor for Form 1 Biology built with LangChain, Pinecone, GPT-4 Turbo, FastAPI, and Next.js. Supports curriculum-grounded summarization, revision Q&A, and free-form tutoring in both English and Swahili.
Full-stack conference platform supporting authentication, registration, mentorship matching, and event workflows for Harvard WECode. Built with React, Supabase, and modular backend services.

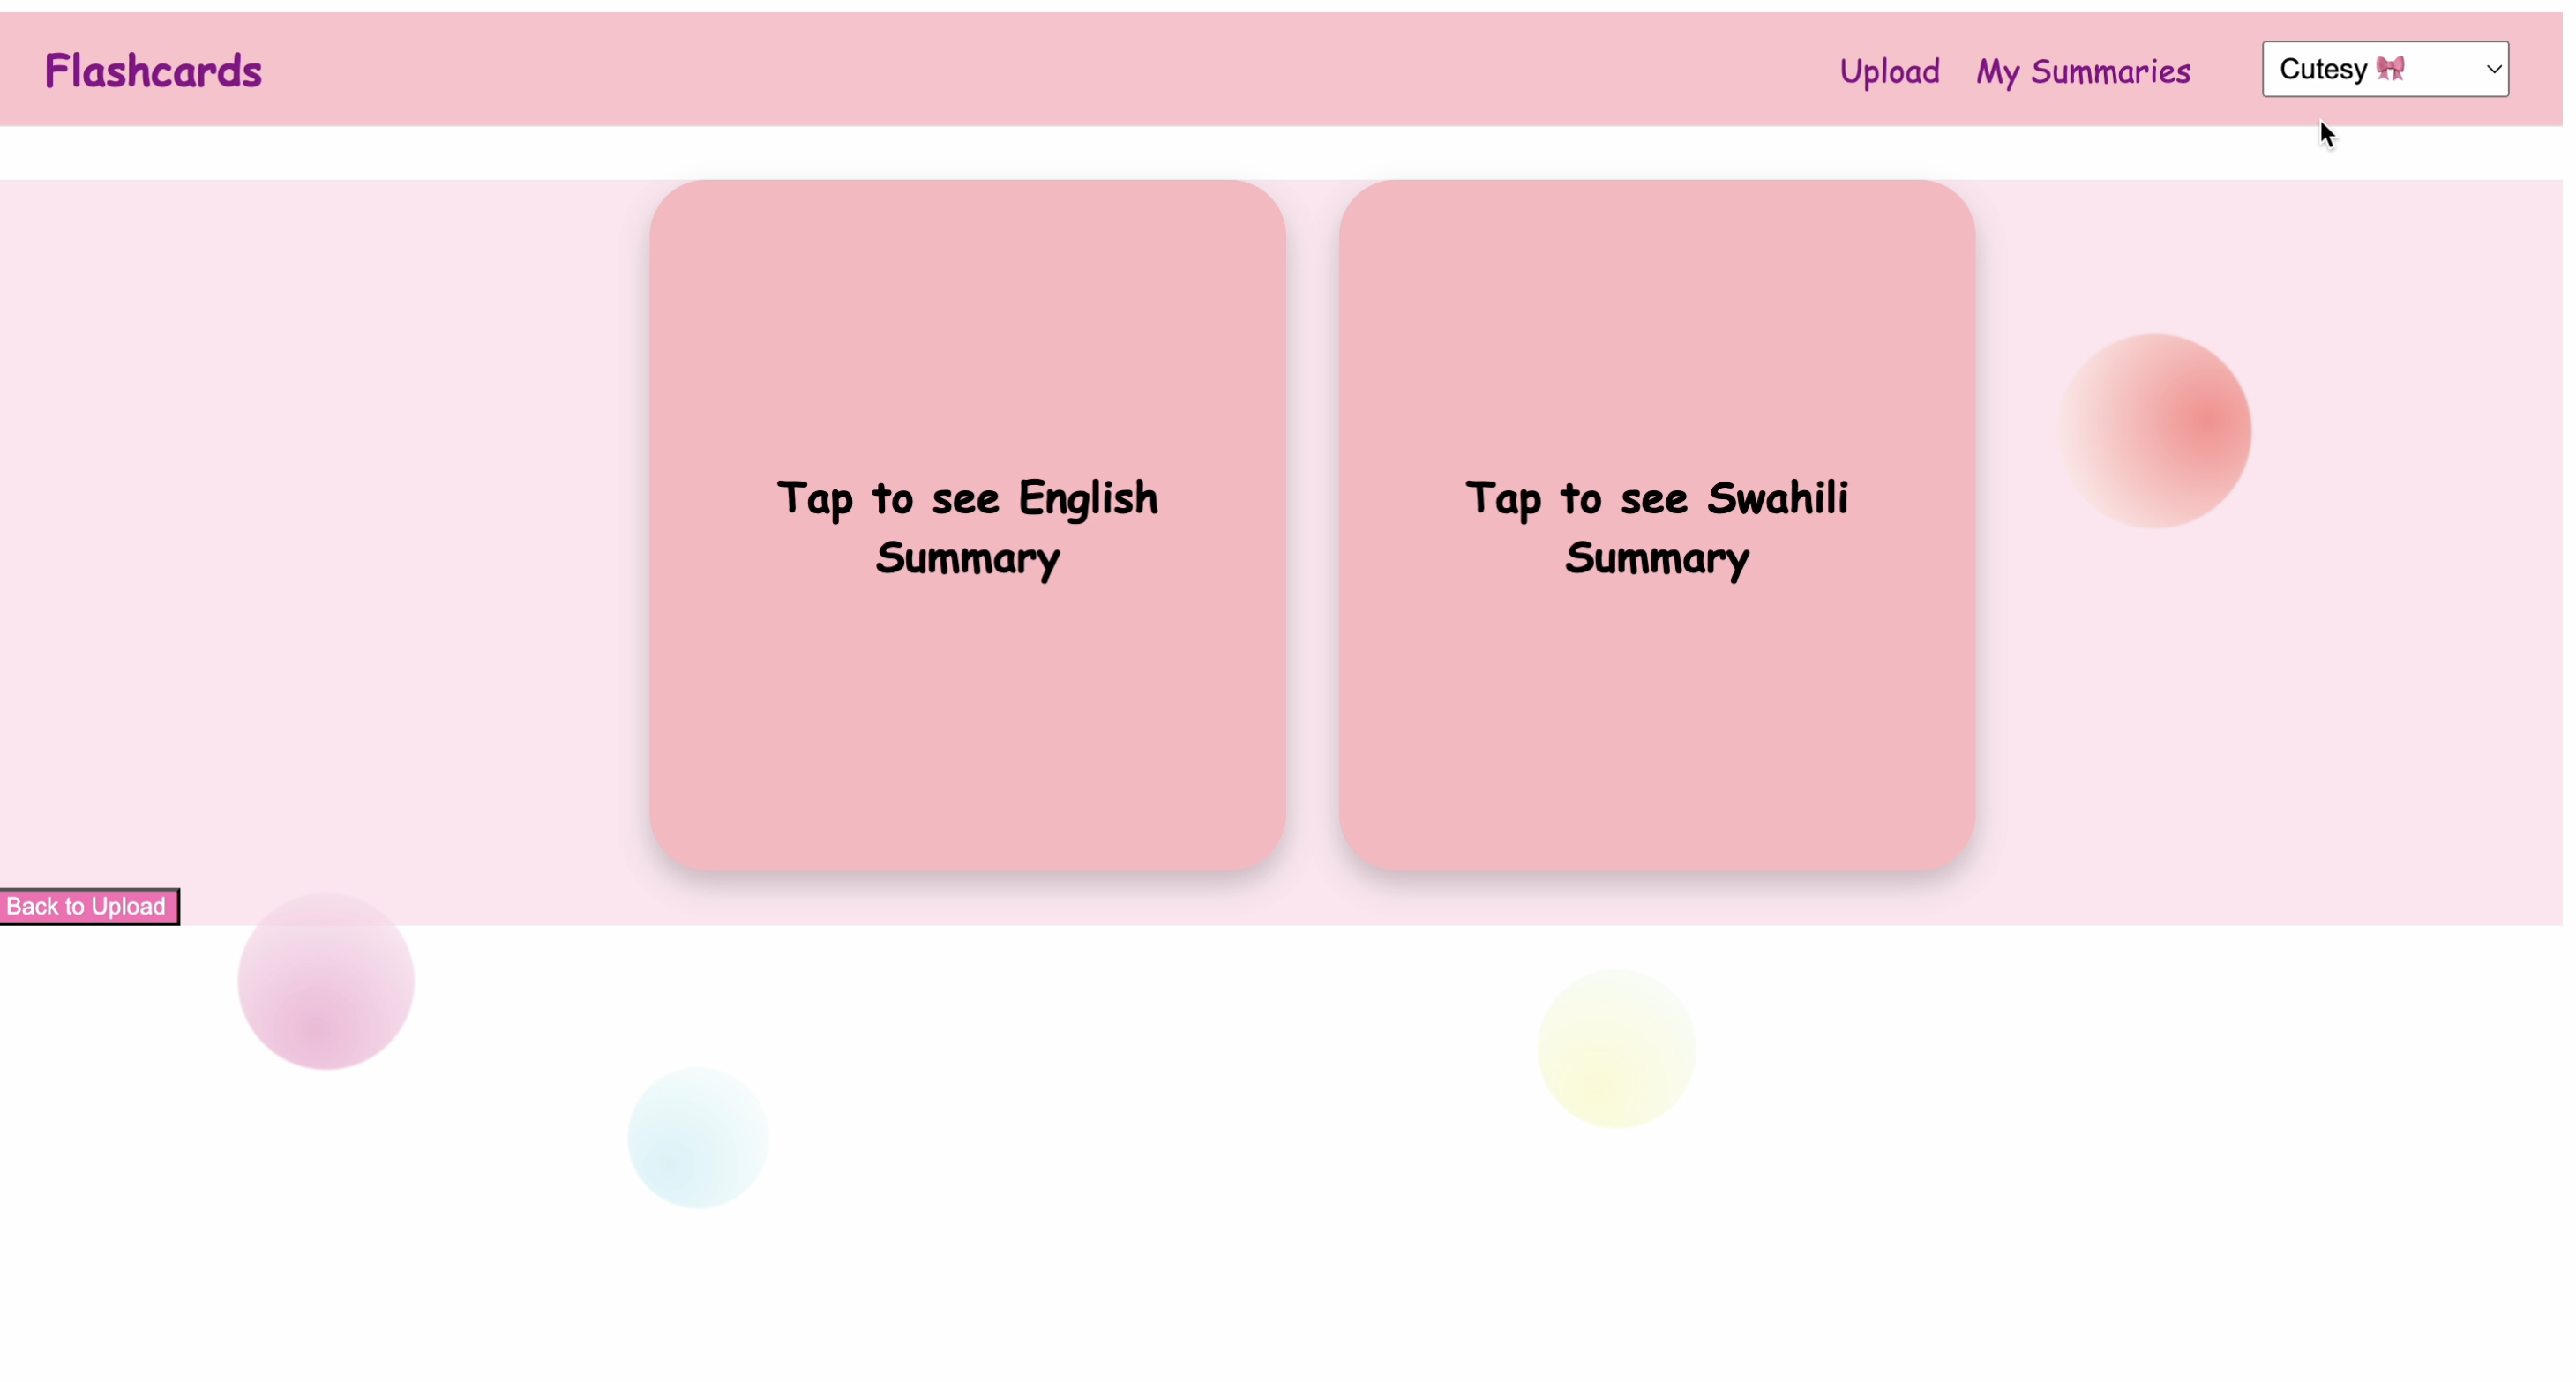
Interactive learning application that generates English and Swahili flashcards, AI study summaries, and text-to-speech audio, with caching and session-state optimizations for faster responses.
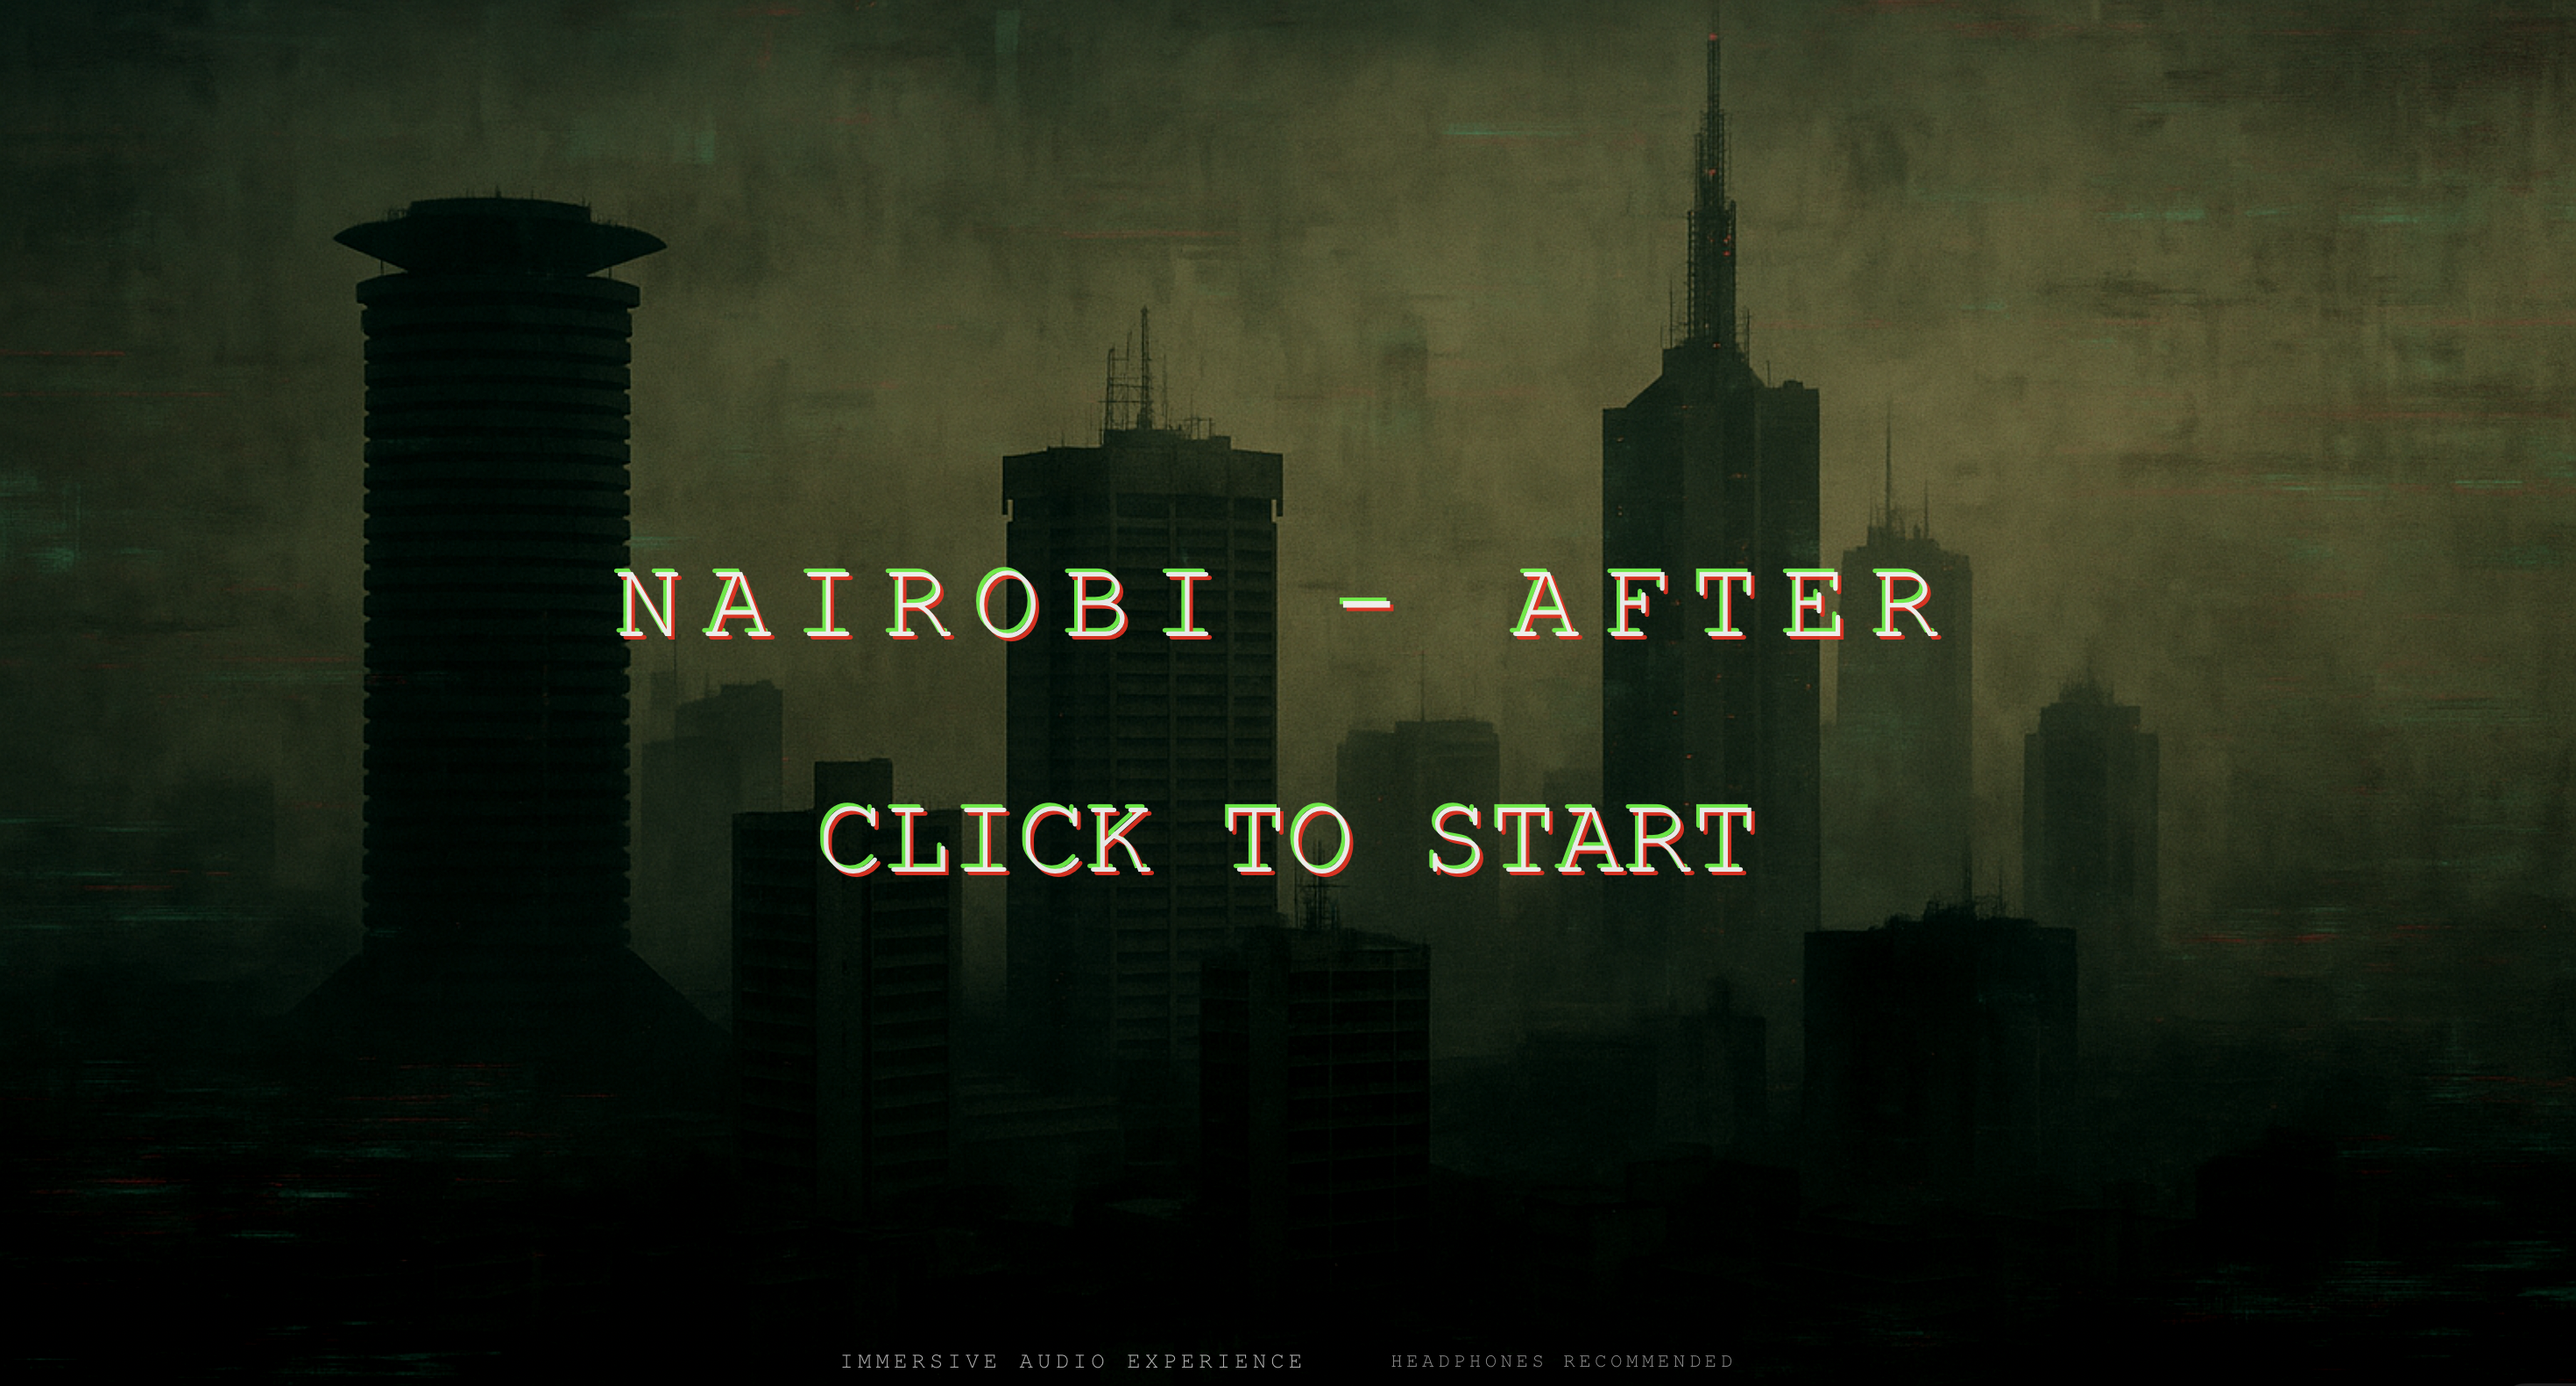
Interactive digital narrative built with HTML, CSS, and JavaScript, combining scroll-based storytelling, glitch animations, ambient soundscapes, and dynamic chapter transitions.
I'm a Harvard student studying Computer Science and Economics, interested in building AI systems that turn complex data into useful, grounded products. Most recently, I interned at LinkedIn, where I worked across labor-market intelligence, Economic Graph data pipelines, and recommender-system evaluation. I built systems that transformed large-scale labor-market signals into grounded evidence for generated insights, developed an end-to-end pipeline for identifying high-growth company opportunities, and extended evaluation infrastructure for LinkedIn's HERO Generative Recommender. My earlier work includes bilingual AI tutoring systems, healthcare software, and multi-agent learning tools. I also serve as Associate Director of Engineering for Harvard WECode and as a Project Lead within the Harvard Undergraduate Machine Intelligence Community.
LLM pipelines, hypothesis-driven retrieval, source evaluation, grounding, provenance, and evidence quality.
Python, SQL, PySpark, Flyte, OpenHouse, large-scale data pipelines, and reproducible evaluation workflows.
Benchmark construction, slice-aware semantic metrics, train/eval separation, and large-scale model validation.
FastAPI, PostgreSQL, MySQL, REST APIs, Docker, and production-oriented service design.
React, Next.js, Tailwind, Supabase, and end-to-end development of user-facing applications.
AI systems spanning labor-market intelligence, education, healthcare, and personalized learning.